ICMI 2026 · RESEARCH PAPER
Multimodal Rapport Estimation in Real-World HRI
1 Japan Advanced Institute of Science and Technology (JAIST)
2 CyberAgent 3 The University of Osaka
Understanding interaction quality in the real world
How can we estimate the quality of a conversation between people and a robot outside the laboratory? We study third-party-rated rapport in 62 robot–customer interaction sessions recorded in a Japanese drugstore.
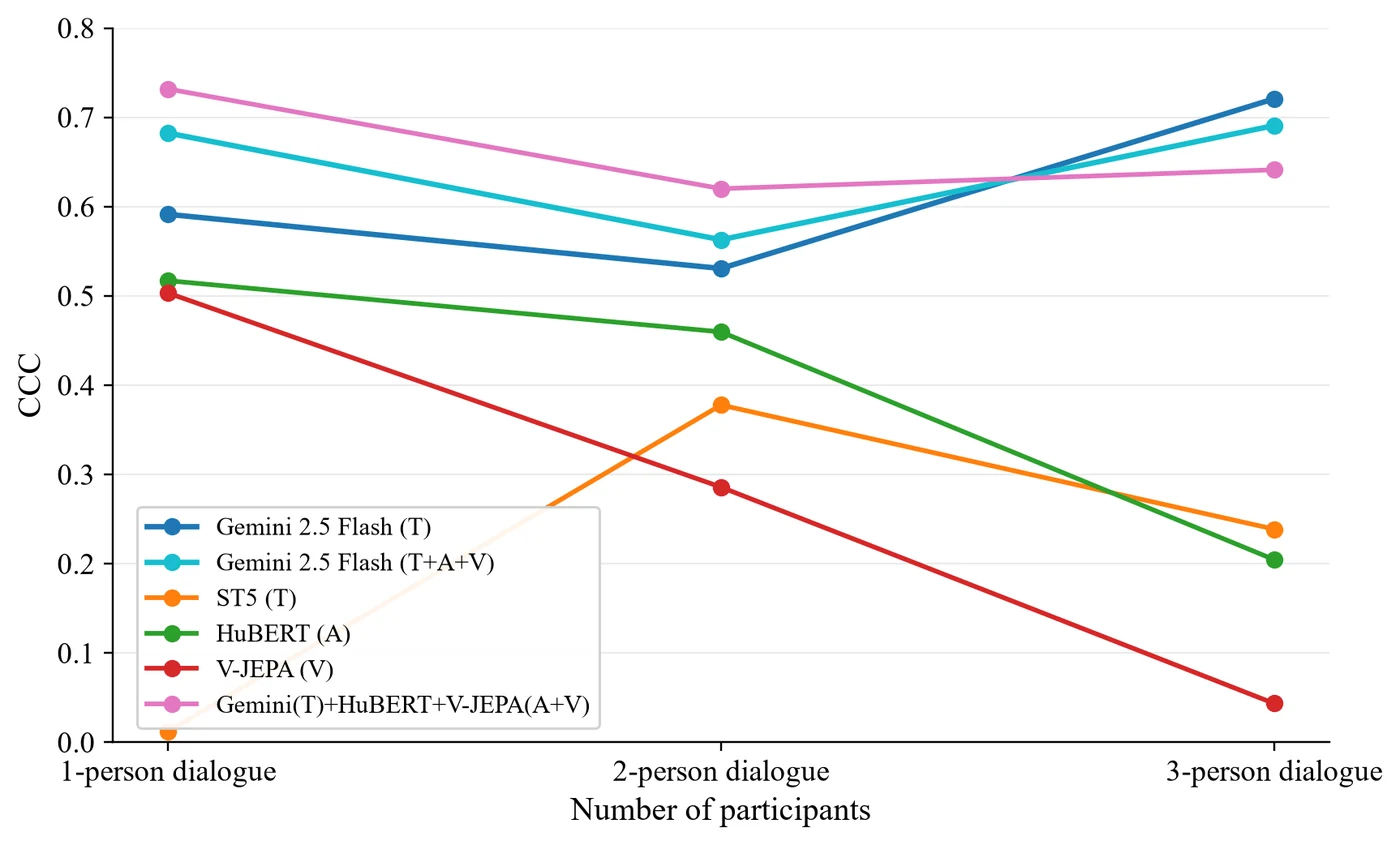
We compare zero-shot language models, pretrained text, audio and visual models, and prediction-level fusion. Combining Gemini 2.5 Flash text predictions with HuBERT audio and V-JEPA visual predictions performs best overall. Performance also varies with interaction duration and group size.
日本語で概要を読む
実店舗での人とロボットの対話を対象に、第三者が評定したラポール(関係の質)を推定する研究です。 日本のドラッグストアで収録した62セッションを用い、テキスト・音声・映像のモデルを比較しました。
Gemini 2.5 Flashのテキスト予測と、HuBERTの音声予測・V-JEPAの映像予測を組み合わせた手法が、全体として最も良い性能を示しました。 対話時間や参加人数によって性能が変わることも確認しています。
Research materials
- Paper on the ACM Digital Library — ICMI '26, Napoli, Italy, October 5–9, 2026.
- Preprint on arXiv — the publicly available version.
- EscortAI Dataset — dataset overview from CyberAgent AI Lab.
- Source code on GitHub — code for the paper.
- Poster — being prepared.
Cite this paper
@inproceedings{sakuramoto2026rapport,
  author    = {Sakuramoto, Akihiro and Hayashi, Takato and Miyoshi, Ryo and Okafuji, Yuki and Okada, Shogo},
  title     = {Multimodal Rapport Estimation in Real-World HRI},
  booktitle = {Proceedings of the 28th International Conference on Multimodal Interaction},
  series    = {ICMI '26},
  year      = {2026},
  address   = {Napoli, Italy},
  publisher = {ACM},
  doi       = {10.1145/3776574.3831184}
}
Research groups & related links
- Okada Laboratory · JAIST
岡田研究室(社会的信号処理・マルチモーダルインタラクション研究室) - CyberAgent AI Lab
サイバーエージェント AI Lab